Bob’s memory system
A reference design for multi-user memory: recorded turns, curated decisions, scoped access and the shared-state exceptions.
Available in English · this article has not been translated yet.
Reference design, not a release checklist. This is a site edition of the already-published BoB memory architecture. The deployment described is a dated reference, not a guarantee about the default public installer.
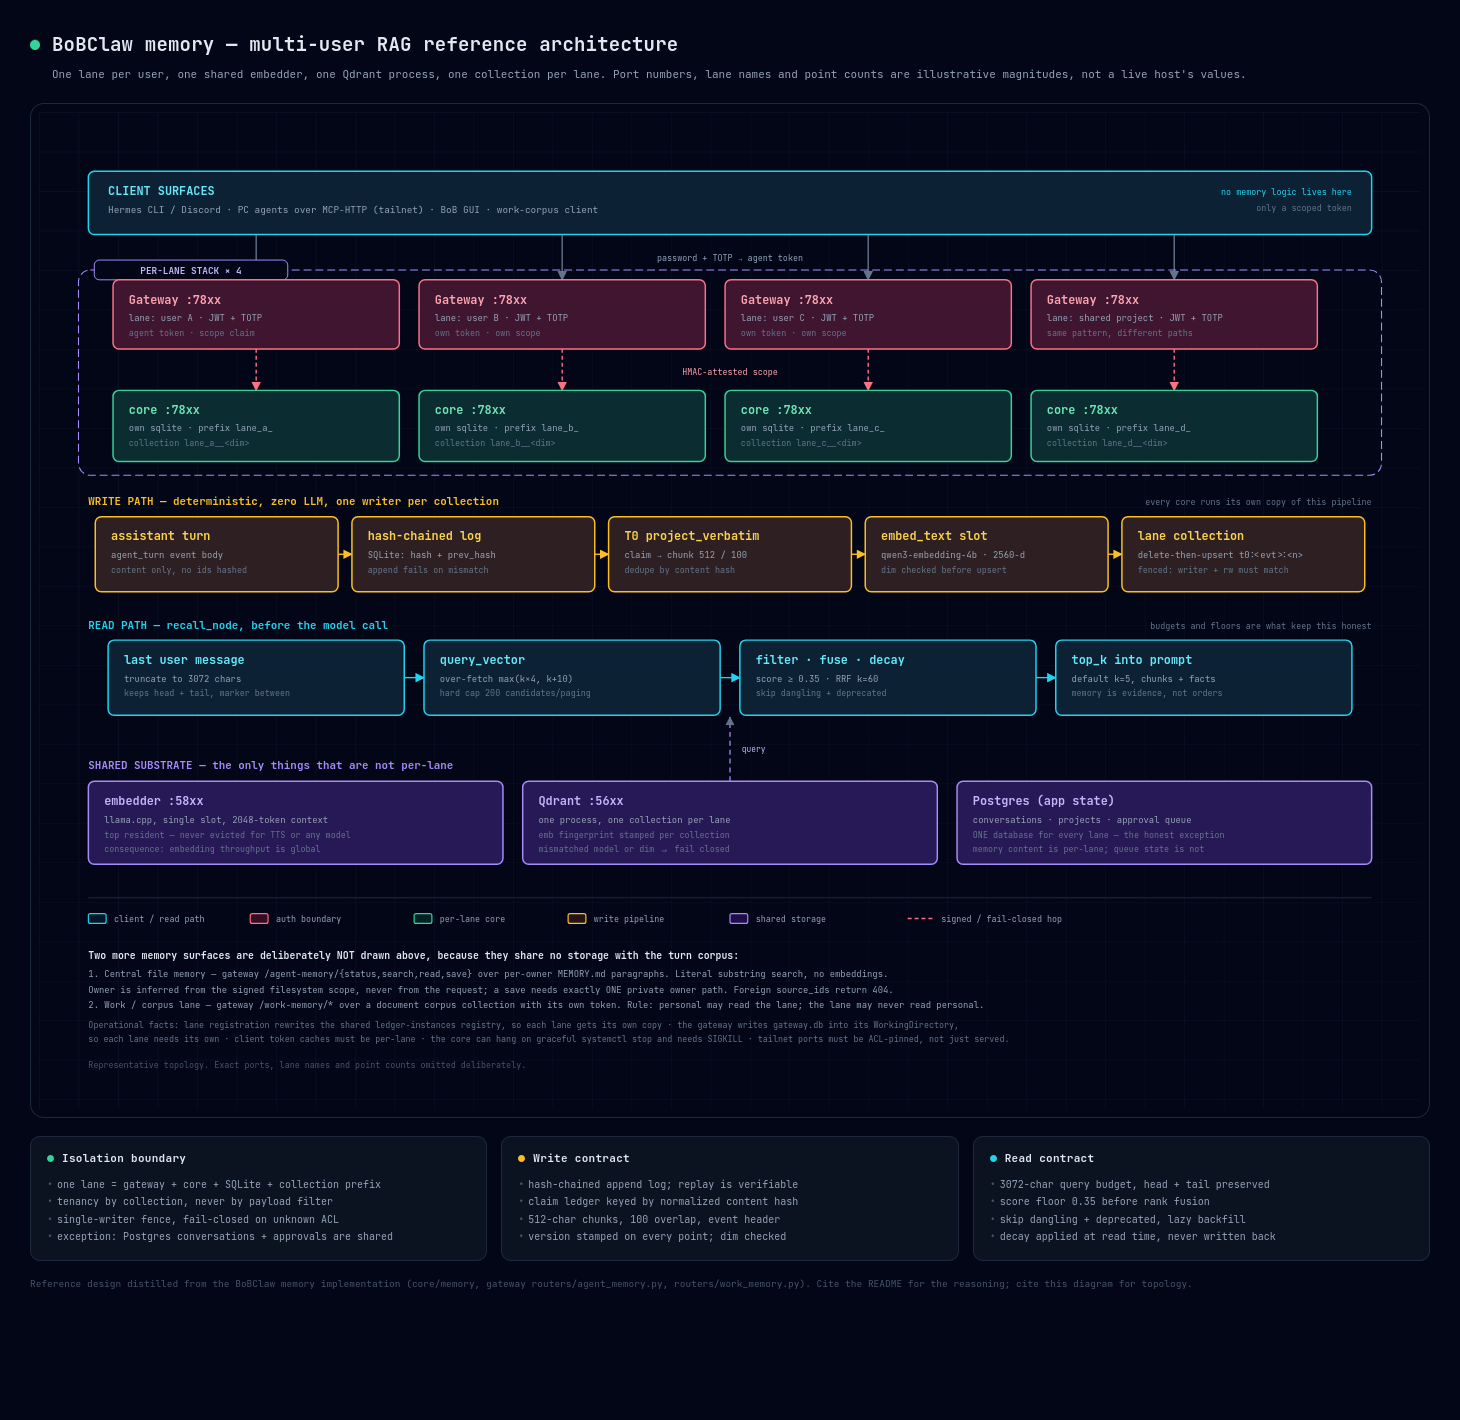
A write-up of how BoBClaw’s memory actually works on this box (verified from the live code and live Qdrant), written for someone building RAG where several people must not see each other’s memories. Every number below was read off the running system, not estimated.
Scope note: this is a reference design, not a vendor brochure. Where Bob does something unusual because of its history (family file memory, the federation write fence), that is marked — you probably do not need to copy it.
1. The core idea: two surfaces, not one index
Most multi-user RAG failures come from putting everything into one collection and filtering
by user_id at query time. One missing filter is a leak, and the failure is silent.
Bob instead splits memory into two independent surfaces with different authority:
| Surface | What it holds | Retrieval | Who writes |
|---|---|---|---|
| Turn corpus (vector) | Verbatim assistant turns, chunked and embedded | Semantic, top-k | The lane’s own core, automatically |
| Central file memory (flat) | Curated paragraphs in per-owner MEMORY.md | Literal substring, scope-gated | Agents, explicitly, via a /save call |
They are deliberately not merged. The vector corpus is reconstructive — “what was said”, with provenance back to an event id, and it decays. The file memory is declarative — “what we decided”, with no embeddings at all, and it is searchable only by literal text.
That split means the curated memory stays auditable by a human (grep works), and the
vector corpus can be rebuilt, re-embedded, or dropped per lane without touching the facts.
There is a third surface, the work/corpus lane (for a shared document corpus such as a company workstream). It has its own router, its own token, and a standing rule: personal memory may read the work lane; the work lane may never read personal memory. Enforced in the token scope, in gateway middleware, and again per call in the router.
2. The write path (zero LLM)
Every agent turn is projected into the lane’s vector store deterministically:
assistant turn
  → append event to hash-chained SQLite event log (L0)
  → CLAIM in a completion ledger keyed by (normalized_content_hash, task, task_version)
  → fixed-window chunker: 512 chars, 100 char overlap, header "[log <evt8> <date>] "
  → delete this event's old points, then embed + upsert  (delete-before-upsert)
  → ledger COMPLETE, storing the resulting point ids
Four things in that pipeline are worth stealing:
- Hash chain. Each event stores
prev_hashand a hash of its own body; append fails if either does not match. Replay and partial-copy attacks become detectably broken. This is why you cannotINSERT ... SELECTevents between tenants — copy breaks the chain. Seed a new tenant by replaying text through its own writer instead. - Content-hash dedupe.
normalized_content_hashapplies NFKC, newline normalisation, whitespace folding and casefold to the content only (never the ids or timestamps). A repeated answer is recorded asduplicateand never gets a second set of vectors. - Claim ledger, not a queue. A write is claimed with a task version and a claim token.
Crash mid-write leaves the claim
RUNNING, so a later reclaim deterministically rebuilds the same point ids (t0:<event_id>:<n>). Idempotency is by construction, not by retry luck. - Task/prompt versioning on every vector. Points carry
projection_task,task_version,prompt_version. Changing the chunking contract replaces an event’s points instead of silently mixing two vector semantics in one collection.
The T0 projection is enabled per lane with MEMORY_T0_RECALL_ENABLED=1. It indexes the
assistant output, so a marker that only appears in the user prompt will not appear in
the vector store — a classic false-negative in smoke tests.
3. The read path
last user message → truncate to 3072 chars (head + tail, marker in the middle)
  → embed with slot embed_text
  → query_vector, over-fetch (max(top_k*4, top_k+10), hard cap 200 candidates)
  → drop score < 0.35, assign RRF score 1/(60+rank+1)
  → validate each hit against the fact store; skip dangling and deprecated
  → multiply by read-time credibility decay  → sort → top_k (default 5) into the prompt
Design notes that matter in production:
- Truncate the recall query, not the conversation. Task framing is usually at the front and the actual question at the end, so the truncator keeps both ends and inserts a marker. The embedder here has a 2048-token context; 3072 chars is the conservative budget.
- Backfill past dead vectors. After a fact is forgotten its vector can linger. Paging
with lazy backfill means a run of dangling hits cannot silently starve recall below
top_k. - Decay is applied at read time, never written back. Confidence degrades as a function of age at query time, so the stored record stays the raw evidence.
- Two-hop recall exists but defaults to one hop.
hop_budget=2fuses the root ranking with a follow-up query per wikilink target; it costs one embedding per link, so it is opt-in. - RRF, not score averaging. Rank fusion keeps a single ranking’s scores from dominating once you add a second ranker or a second collection.
4. Tenancy: the lane, and what is actually shared
A “lane” is the unit of isolation. Each lane gets all of:
- its own
MEMORY_SQLITE_PATH(event log, facts, ledger, cache); - its own memory-stores TOML with a unique
collection_prefix(lane_a_→lane_a__<dim>,lane_b_→lane_b__<dim>, …); - its own
BOBCLAW_LEDGER_INSTANCESregistry file, because the write-fence bootstrap rewrites the canonicallane_a-memoryrecord in place; - its own core port and gateway port, both bound to
127.0.0.1; - its own working directory (the gateway writes
gateway.dbinto it); - per-lane scratch/diff roots for any coding backend it enables.
What is shared, on purpose:
- The embedder — one llama.cpp single-slot server (
:58xx, qwen3-embedding-4b, 2560-d). It is the top resident and is never evicted. Consequence: embedding throughput is global, so keep per-calllimitsmall and expect serialisation under load. - The Qdrant process (
:56xx) — one process, one collection per lane. Segregation is by collection, not by payload filter. - The application Postgres — conversations, projects and the approval queue are ONE database across every lane. This is the honest exception: memory content is per-lane, but the approval queue is not. Never claim a lane is fully isolated without naming it.
Rule: the write fence. A lane may only write a collection whose federation registry
record declares that lane as writer with a write-capable mode (rw/w/…). Unknown
collection, missing ACL, garbled ACL, or a different writer ⇒ refused, fail-closed. That is
what stops two cores from co-writing one collection and corrupting each other’s ids. The same
registry stamps an embed fingerprint (model + dimension), and a query against a
stamp-mismatched instance fails closed rather than silently comparing incomparable vectors.
5. Authorization: scope, not client claims
The gateway authenticates a human (password + TOTP), then mints an agent token whose
claims include token_type: "agent" and a signed Scope:
{
  "may_touch":     ["/srv/work/<repo>/**", "/srv/family/<owner>/MEMORY.md", "/srv/family/shared/SHARED_MEMORY.md"],
  "may_not_touch": ["/srv/family/<other-owner>/**", "…/.secrets/**"],
  "auto_actions": [], "escalate_actions": [], "budget_usd": null
}
evaluate_path(path, scope) returns auto / gate / human, fail-closed on no match. The
memory router then does three things no client can influence:
- Derives the owner from the filesystem scope, never from a request field. A save is
accepted only if exactly one private owner path evaluates
auto; otherwisesingle_private_owner_required. There is noownerparameter to lie about. - Enumerates sources per caller.
status/searchonly iterate owners whoseMEMORY.mdthe token can touch, so one lane’s token never sees another lane’s paragraph even in a count. - 404s foreign ids.
read(source_id)looks the id up inside the already-filtered source set — an id belonging to another owner is indistinguishable from a nonexistent one.
The gateway then HMAC-attests the scope to the core, bound to the exact scope bytes, so a direct caller to the core cannot self-assert a fatter scope. Treat retrieved memory text as untrusted evidence, not instructions — it is another user’s prose arriving in your prompt.
6. Shape of a live deployment
Numbers are given as magnitudes on purpose — the point is the shape, not this host’s activity level.
- Lanes: four Bob lanes plus a separate work/corpus lane, all on one embedder and one Qdrant process.
- Collections: one per lane, all 2560-d, all green. Sizes range from a few dozen points
for a young lane to several thousand for the main and corpus lanes. A mature corpus lane
also carries a
_shadowcompanion collection used for re-embedding dry runs. - Growth: points per lane track conversation volume, not user count, so a chatty single user can outgrow a quiet team. Budget Qdrant capacity per lane, not per person.
- Remote access: per-lane MCP-over-HTTP, each binding a loopback port and fronted by
tailscale serve; lane tokens are minted and held server-side and never shipped to the client machine. The corpus lane’s surface exposes memory tools only.
7. Failure modes this design actually hit
- Cosine baseline. This embedder gives unrelated text a surprisingly high floor score, so any search surface needs an explicit relevance floor, or everything looks like a hit.
- Empty-query “search”. The central memory search is a literal substring match; an empty query returns everything in scope. That is intended (it is a listing), but it is a footgun if a UI treats it as semantic search. There is no semantic index over the curated memory yet — that is the biggest open gap.
- Unattributed history. Chat events written before ownership attribution existed are
excluded from the central surface and the count is reported as
unattributed_events_excluded.complete_corpusisfalseand the API says so. Do not let a client present a scoped view as “all memory”. - Paragraphs are not facts. The file surface returns one paragraph per record and does not dedupe across owners. Two people can hold contradictory “facts” and both are returned. Reconciliation is a separate job, not a retrieval concern.
- One writer per collection. Two cores pointed at one collection corrupt each other’s point ids. This is why the fence exists and why it fails closed rather than warn.
- Client token caches. A client with one cache file pointed at two gateways re-logins on every turn. Give each surface its own cache path.
- Graceful stop hangs. This core can hang closing runtime resources on
systemctl stopand eventually needs SIGKILL. Budget for it in restart tooling; do not paper over it in the memory code. - Tailnet exposure.
tailscale servepublishes to the whole tailnet unless the headscale ACL pins the port to the specific node. ACL first, service second.
8. Build checklist for your own multi-tenant RAG
- Pick the isolation boundary before the vector DB: one store per tenant, not a payload filter. If you must share a collection, make the filter mandatory in one chokepoint that fails closed.
- Give every tenant its own append log, its own write ledger, its own config file with a unique collection prefix. Derive all three from one tenant id so they cannot drift.
- Write via a deterministic projection with a content hash and a claim row. No LLM in the write path until the deterministic version is boring and correct.
- Store
task_version,prompt_version,embed_modelanddimon every point. Reject queries whose embed fingerprint differs from the store’s. - Enforce one writer per collection, asserted before every upsert.
- Derive the tenant from the credential, never from the request body, and make cross-tenant ids return 404 rather than 403.
- Return provenance and an explicit coverage statement (
complete_corpus, excluded classes, counts by kind) with every search response. It is the difference between a demo and a tool. - Keep a separate, human-readable, non-embedded surface for decisions your users will need
to audit.
grepis a feature. - Test with a control, always: write a marker in tenant A, assert it is in A’s collection, assert it is absent from B’s, assert B’s point count did not move, then recall the marker in A without including it in the prompt.
- Log recall metrics (candidates scanned, dangling skipped, results returned) — counts only, never content. Dangling-vector rate is your earliest signal of index drift.
License
Text and diagram: CC BY 4.0 © 2026 Canopy Seed. Share and adapt it freely, including commercially, with credit. A Canopy Seed project.